This feature is currently in development but is available to use. Please note that UI and functionality might change from release to release.
Heads up!
The GPT-OSS model family by OpenAI does not currently support structured output, meaning it is not able to be used for AI Enrichment.
Important tip!
This process often takes a bit of trial and error.
We recommend starting with a small set of sample documents, some relevant and some irrelevant to the prompts you're testing in Shinydocs Pro. This lets you quickly see how the model responds and make adjustments to your prompt or model choice without sifting through a massive dataset.
Different models can interpret prompts differently, and outputs may not always be what you expect. Testing with a small, focused sample helps you dial it in faster.
AI Enrichment allows you to analyze document content and generate structured metadata fields using large language models. These fields can be used for tagging, classification, or extraction during a crawl. Enrichments are defined through prompts and executed conditionally based on the document’s metadata.
This guide will walk you through how to configure your enrichment, what each field does, and how to design effective prompts.
How it works/workflow
-
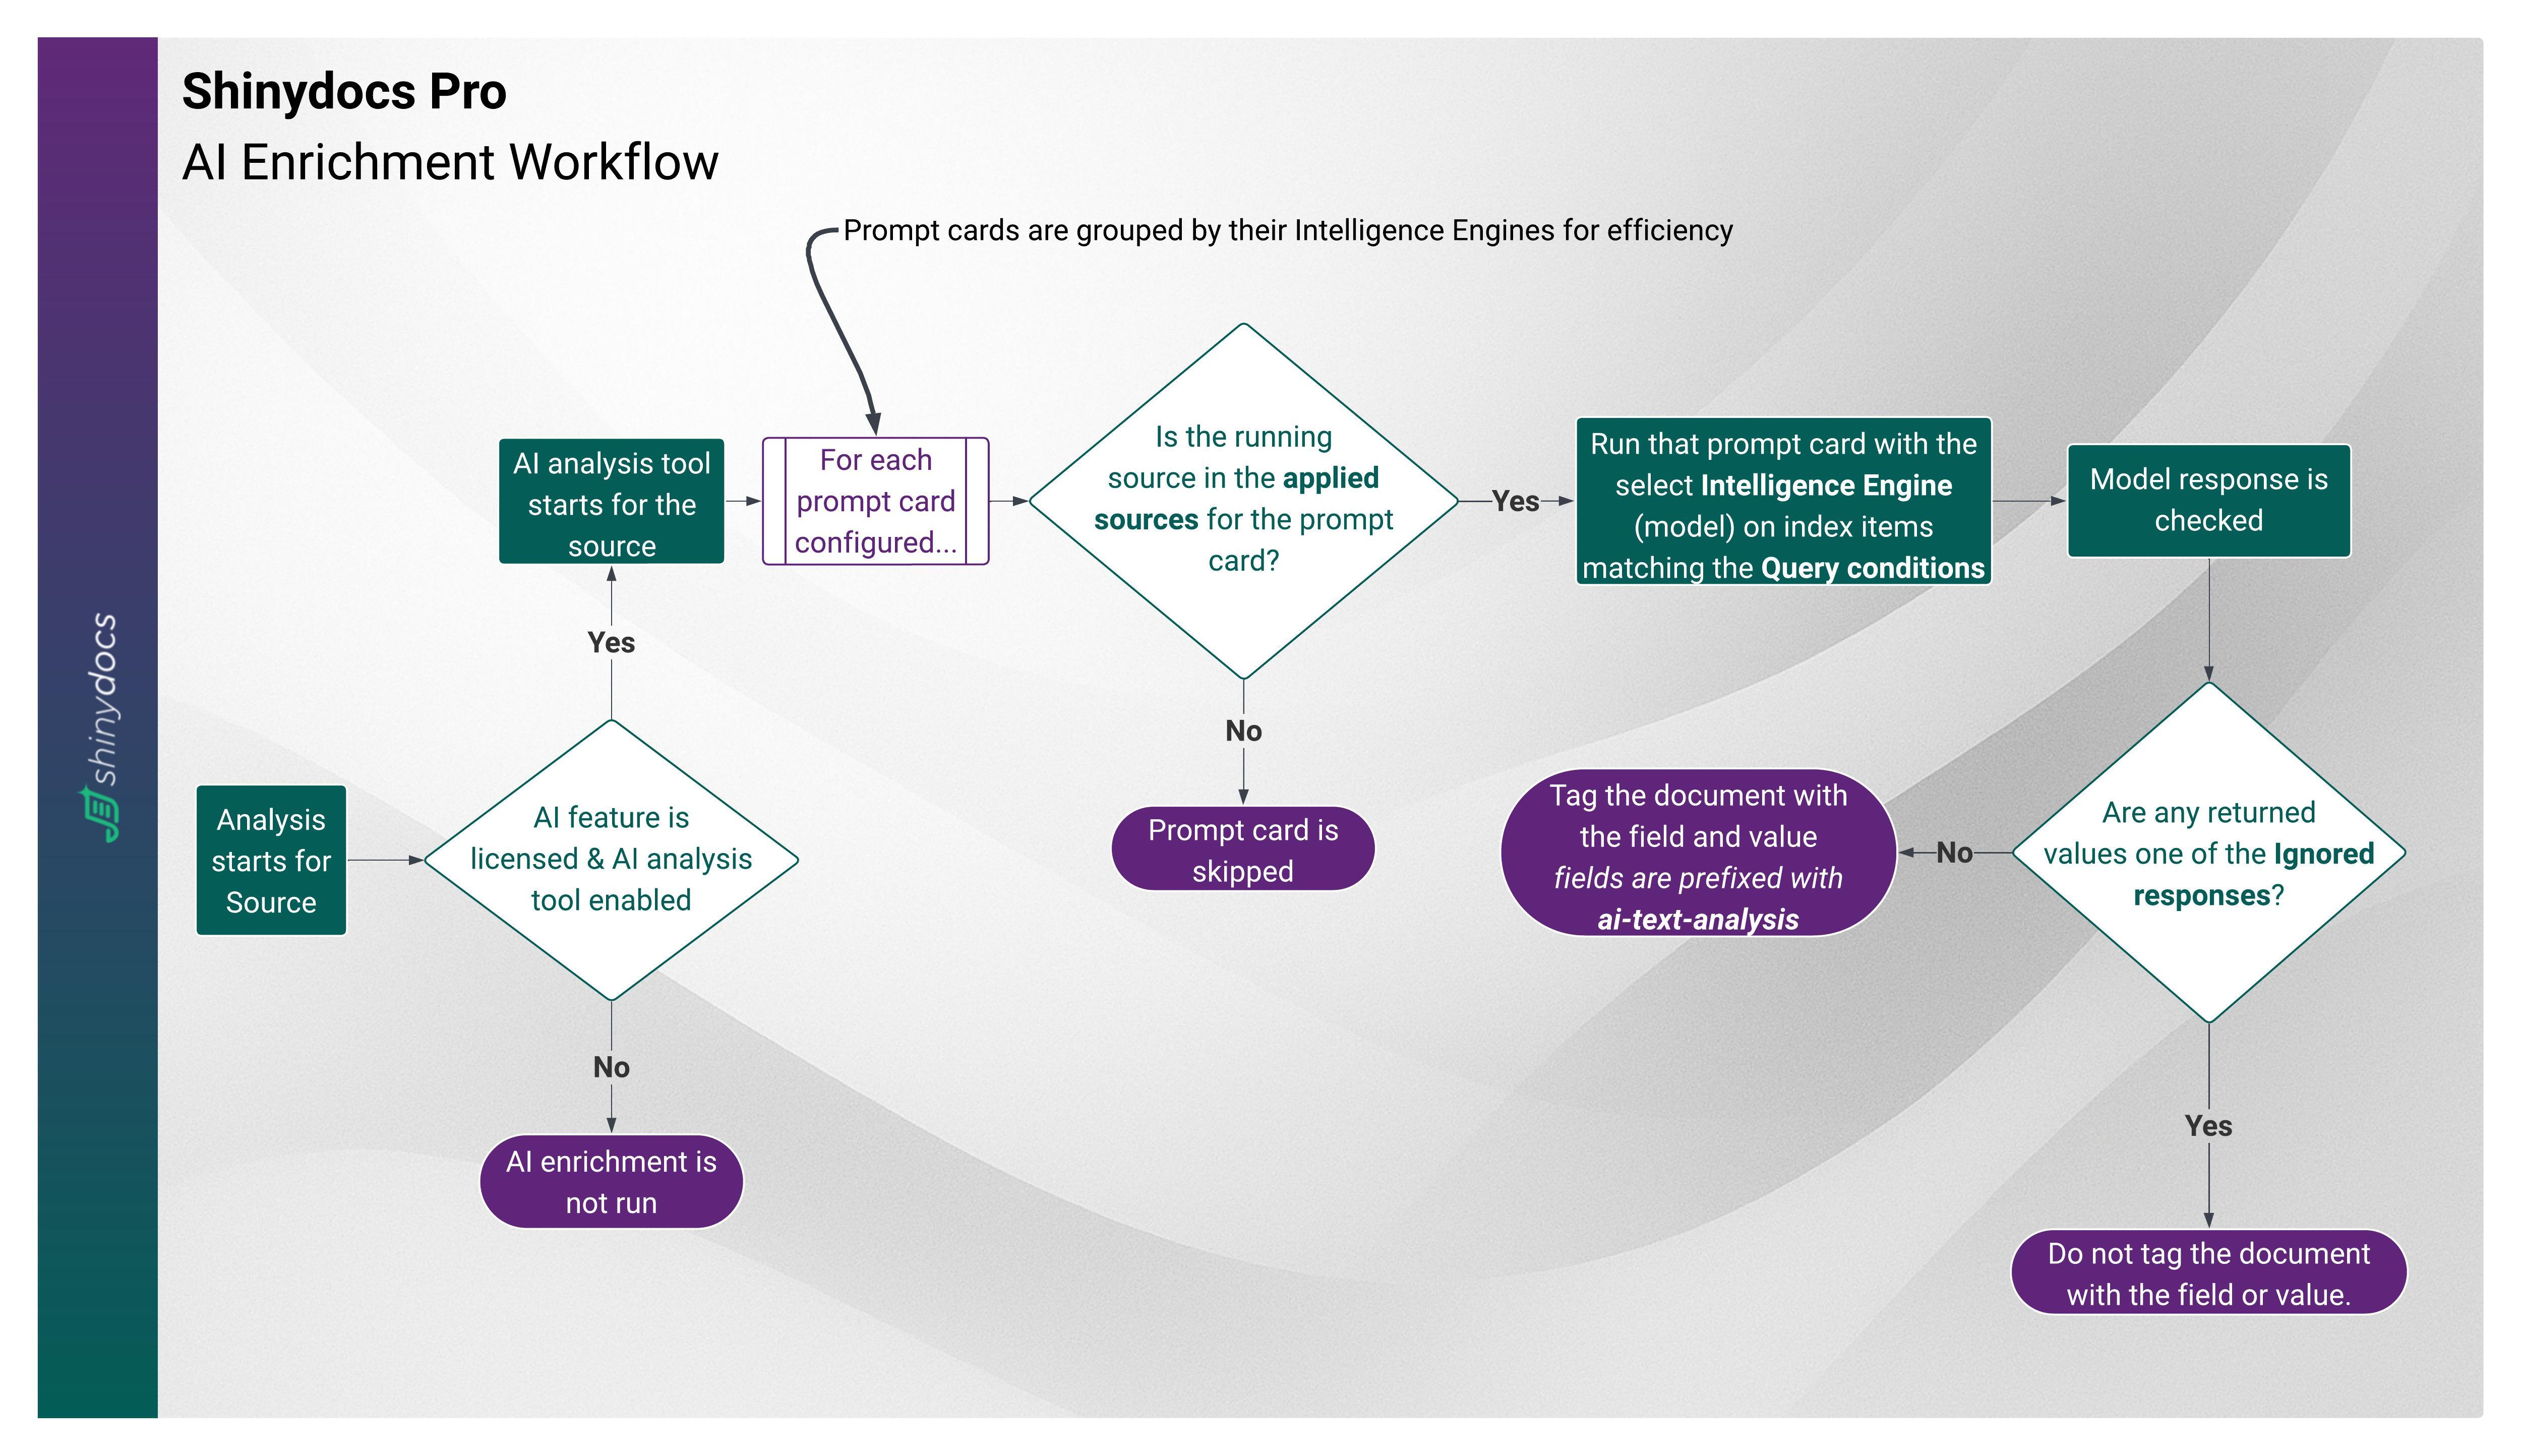
Start of Analysis
When a source's analysis runs, AI analysis runs as its last step, for each source that has AI analysis turned on. It doesn't run when a source only crawls. -
Prompt Cards
Each configured prompt card is grouped by its model for efficiency. The system checks whether the running source is included in the applied sources for that prompt card. If not, the card is skipped. -
Query Conditions
If the source matches, the model processes only the index items that meet the defined query conditions (for example, ensuring the file has text, or that it hasn’t already been enriched). -
Model Execution
The model runs the prompt card against the filtered items. The model’s response is then checked. -
Ignored Responses
If the model returns a value defined as an ignored response (such as “N/A”), the system does not tag the document. -
Tagging Documents
If the response is valid, the document is tagged with the specified fields. All AI enrichment fields are automatically prefixed withai-text-analysisfor easy identification.
Guidelines for AI Enrichment
-
Use ISO date format
If requesting date/time information, always ask in the system prompt to
return or normalize dates in ISO 8601 format (YYYY-MM-DD or YYYY-MM-DDTHH:mm:ssZ). -
Start with small test sets
Test your prompts and model choice on a small set of documents first to refine results before scaling up. -
Pick the right model for the task
-
Small models (≤1b): fast, good for summarization, tagging, or simple classification.
-
Larger models (≥8b): slower, better for extraction, detailed classification, or complex analysis.
-
Very large models (≥ 30b): only use these models on small datasets that are very complex. These models take a long time to produce a response.
-
-
Be specific in prompts
Write prompts as if you’re instructing a junior analyst. State exactly what you want returned and how to handle uncertain cases. Use{{text}}to inject document content. -
Set query conditions
Always define conditions to control when enrichment runs. Common examples:-
fullText | exists(only process files with extracted text) -
path-valid | is not | false(skip deleted files) -
Skip files already enriched by checking if enrichment fields exist.
-
e.g.
ai-text-analysis-summary | does not exist
-
-
-
Handle uncertain or null results
Define ignored responses likeN/Aor[N/A]so they don’t get written as real values. -
Define result fields properly
-
Mark a field Required when the model must always answer it. Fields that aren't required can be left empty.
-
Primarily use Text field types.
-
Use Number only for values that can only be numeric (using it incorrectly will cause errors).
-
Use List of text only when you expect multiple values (like keywords).
-
-
Use the seed option for consistency
Setting aseedensures the model gives repeatable results during testing. Seed and temperature are set on the model, under Settings > Intelligence > Models. -
Control randomness with temperature
-
Use 0.2–0.5 for reliable results.
-
Use 0.0 if asking the model to find content that exists in the system prompt
-
Use higher values only when creativity is more important than consistency.
-
-
Save before running
Prompts run when a source's analysis runs, so make sure you save all changes to prompts and fields first.
Turn on the feature
AI analysis needs the Intelligence Engine add-on on your license. Contact Shinydocs for details.
-
Add a provider and check that it has a model that generates text. See the Intelligence Configuration Guide.
-
Open the feature flags page at
https://<server>:9701/settings/flagsand turn on AI Analysis Tool. It shows the AI tab under Settings > Analysis and the AI analysis step on each source. -
Go to Sources, open each source you want to enrich and turn on AI analysis in its Analysis panel.
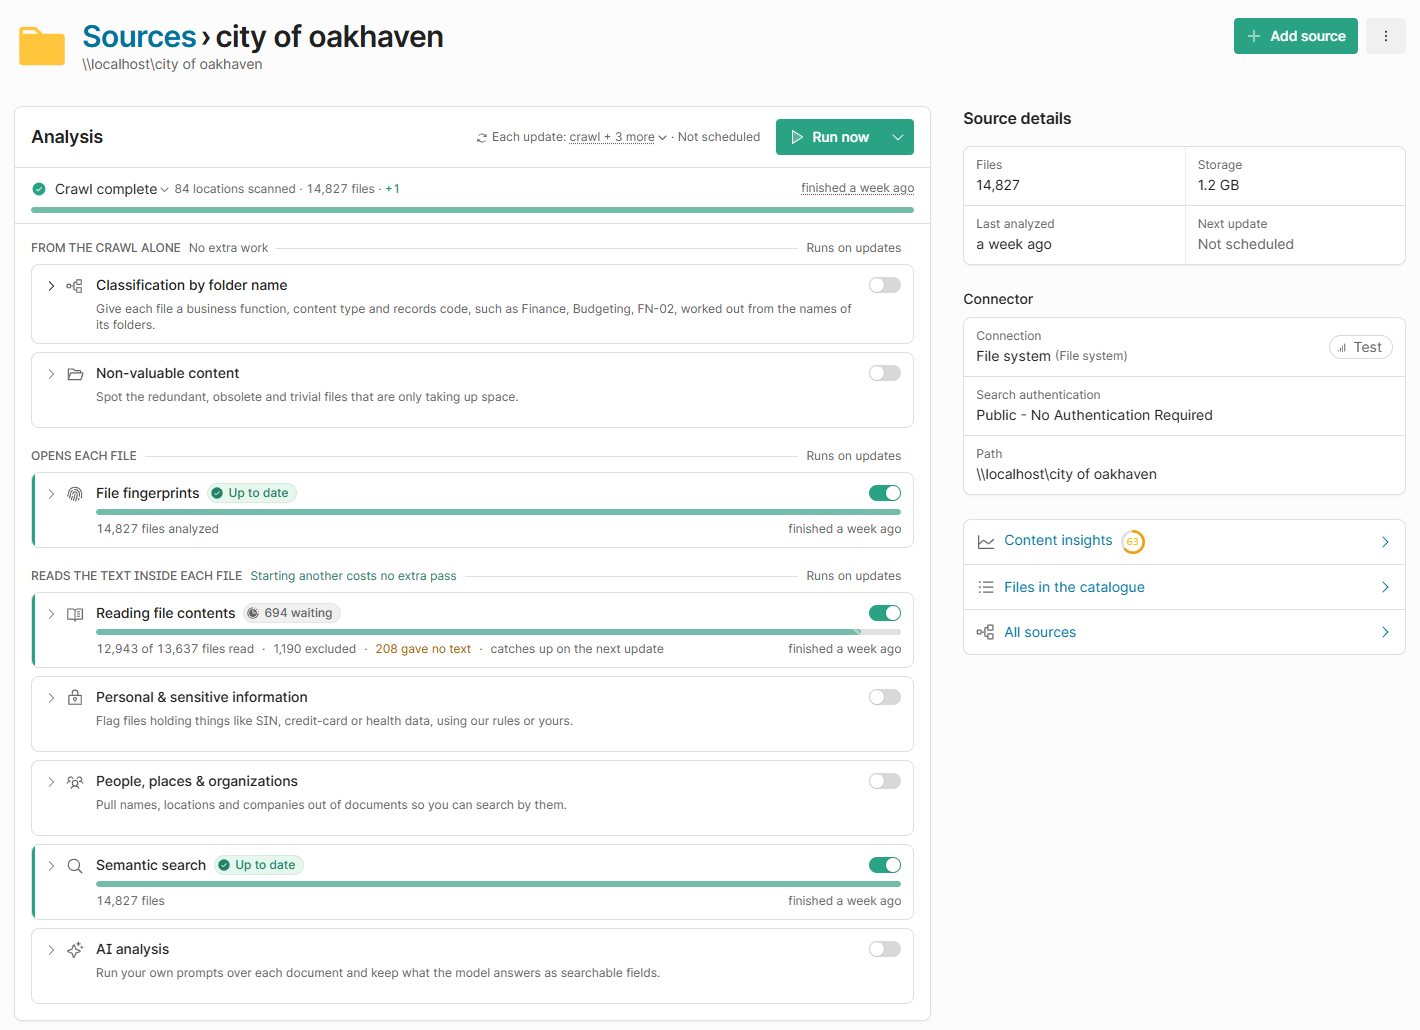
Turn AI analysis on only for the sources you are testing with. Running prompts over a large source can take a long time.
Step 1 - Add a prompt
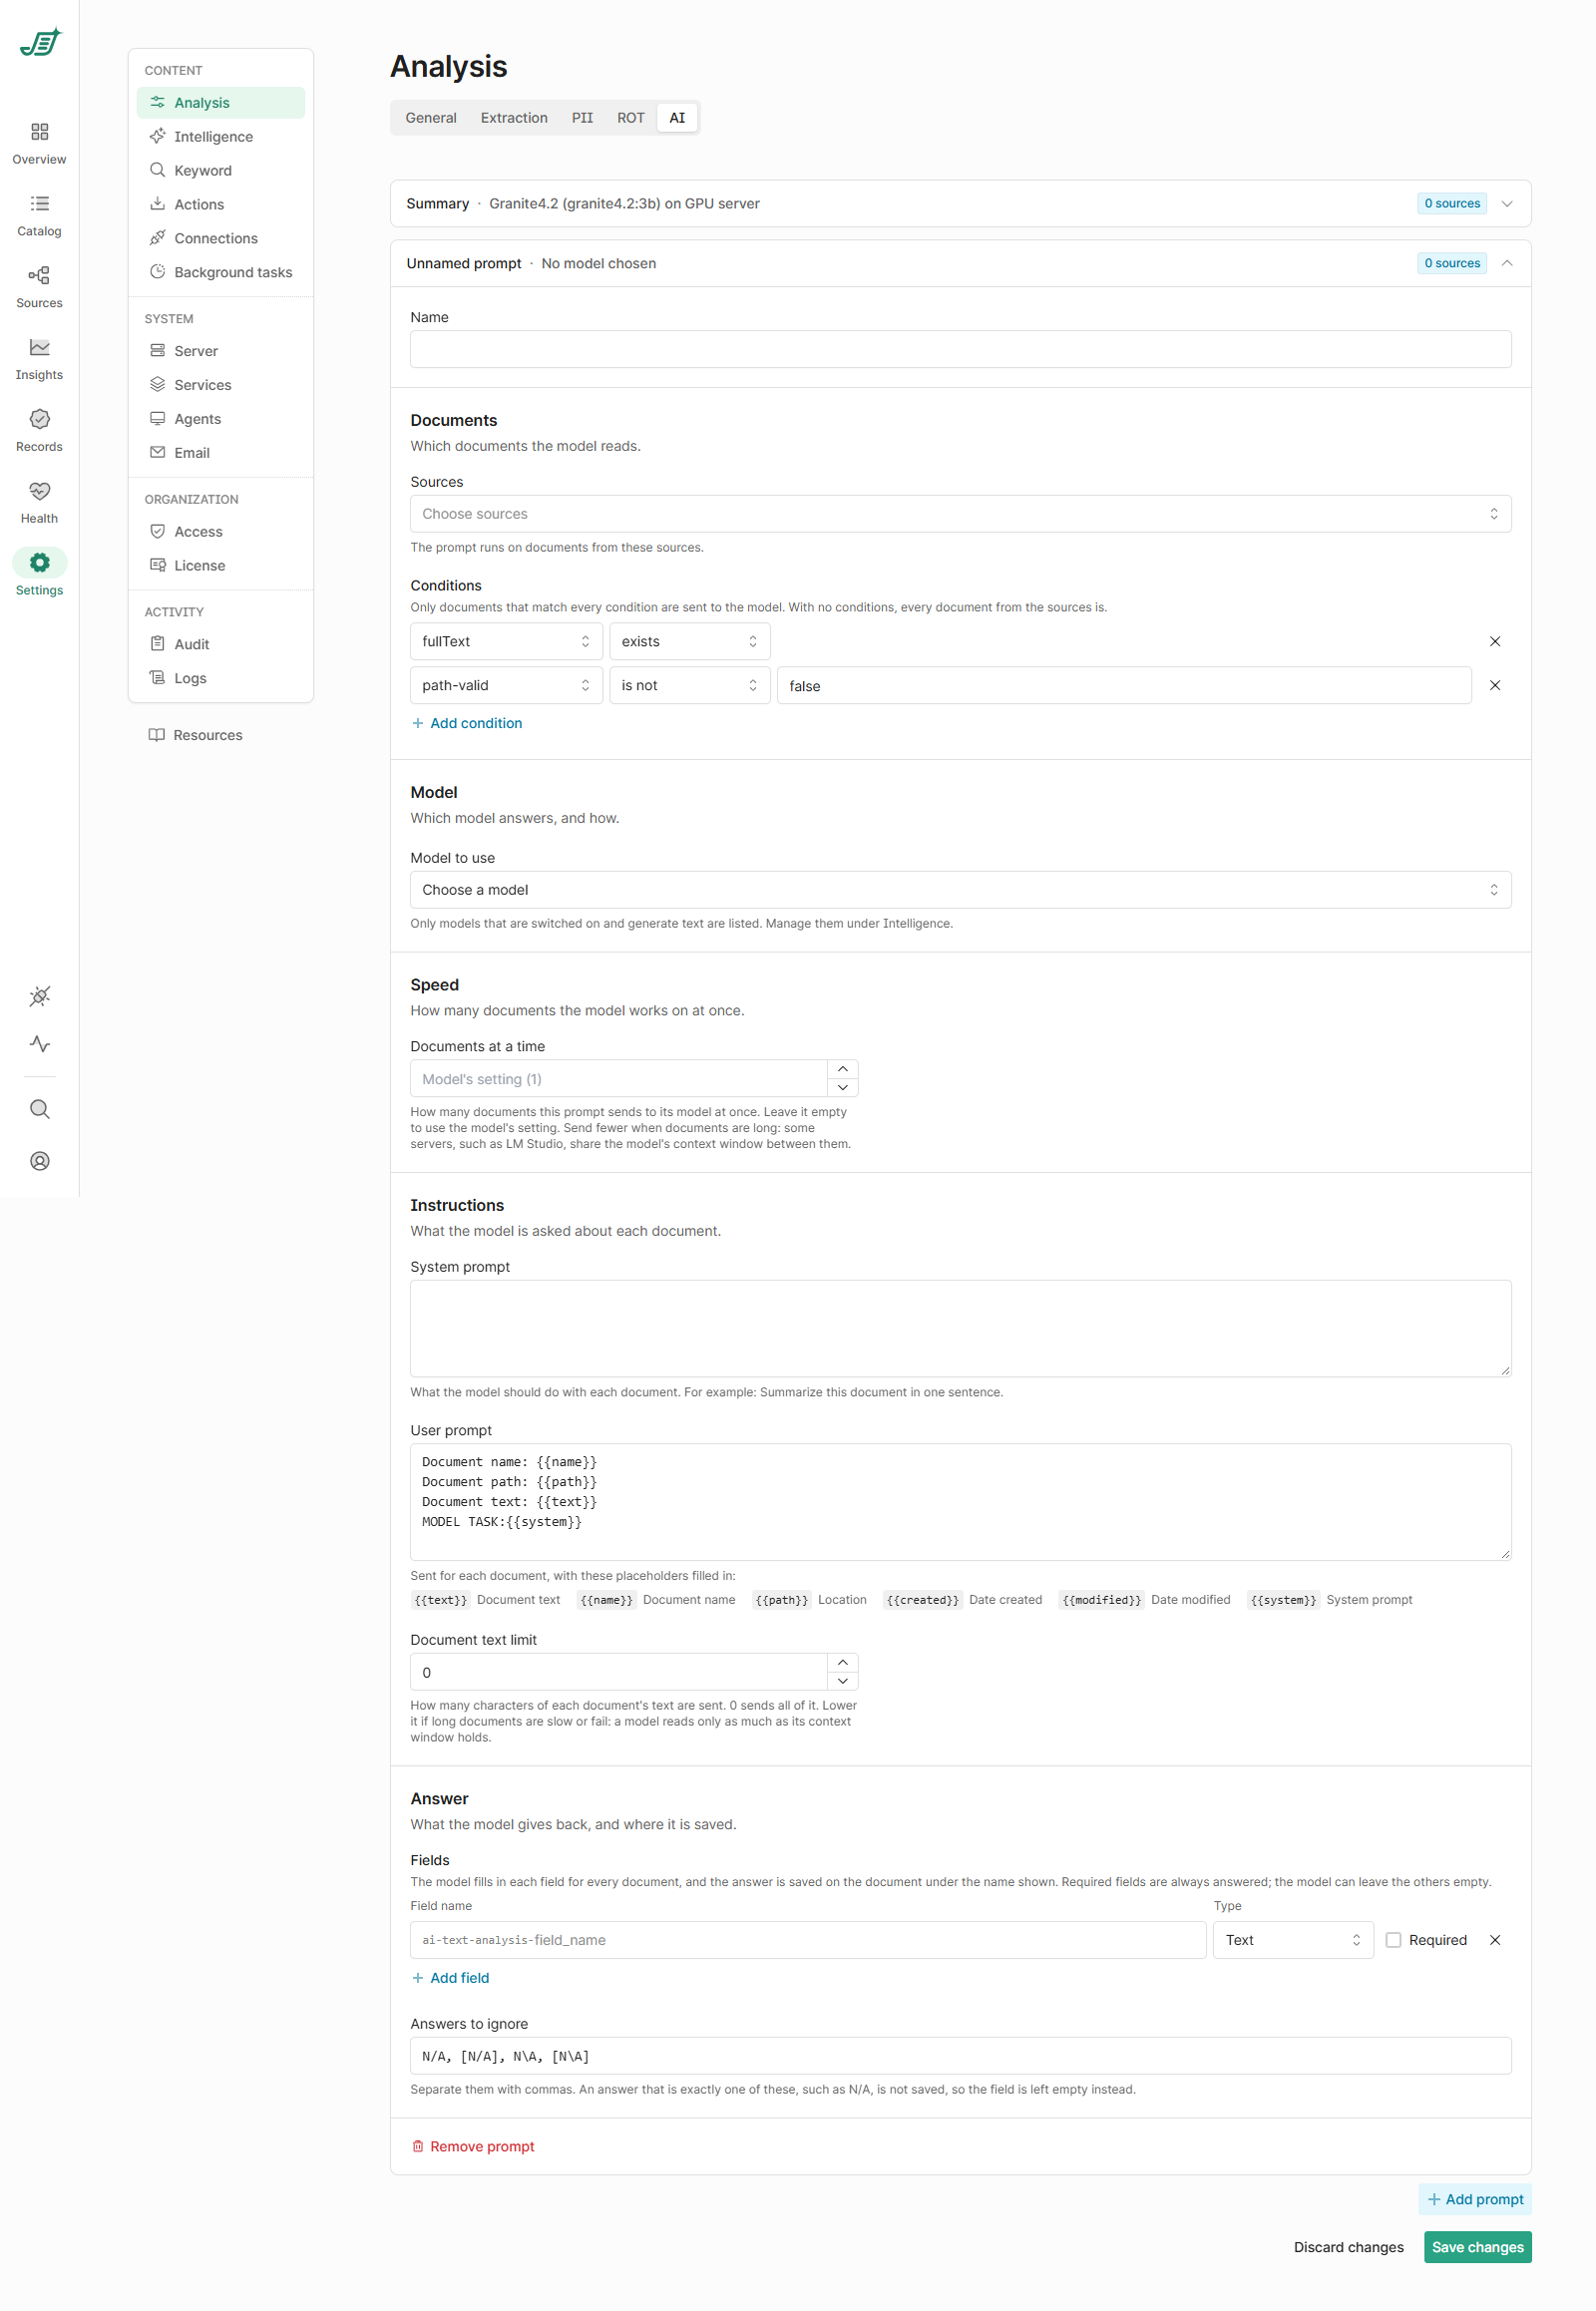
Go to Settings > Analysis and open the AI tab. Each prompt is a card showing its name, its model and how many sources it applies to. Select Add prompt, then give the prompt a Name.
Step 2 - Choose the documents
Under Documents, use Sources to choose which sources the prompt runs on. New sources are not added automatically. The Conditions narrow it further; see Step 5.
Step 3 - Choose the model and speed
-
Model to use: only models that are switched on and generate text are listed. Manage them under Settings > Intelligence.
-
Documents at a time: how many documents this prompt sends to its model at once. Leave it empty to use the model's Maximum threads setting. Send fewer when documents are long: some servers, such as LM Studio, share the model's context window between them.
A larger model gives better answers but takes longer per document. For simple tasks such as a topic or a document type, a small model is often enough; test before you scale up.
Options such as temperature, seed, top K and the context window are now set on the model, not on the prompt. Open the model under Settings > Intelligence > Models and expand Advanced Options. To use different options for different prompts, add the same model twice with different nicknames.
Step 4 - Write the Prompts
System Prompt
The system prompt defines the role and goal of the model. This is what sets context for the model's behavior and should explain the task in simple but precise terms.
Important tip!
Write this like you're briefing a junior analyst. Be specific about the task, what you expect returned, and how to handle uncertain cases.
Example
You are a data extraction assistant. Your task is to analyze a document and determine if it pertains to any of the client matters listed below. If you identify a match, return all fields from the matching row exactly as shown. If you are not sure or cannot confidently match the document to a matter, respond with "N/A".
User Prompt
This is where you inject the actual text of the document. Use {{text}} in your prompt to insert the full document content that Shinydocs Pro extracted during the crawl. The User prompt is usually much simpler than the System prompt.
Available placeholders:
|
Placeholder |
Use |
|---|---|
|
|
Replaced with the text data Shinydocs Pro has extracted for the document. Index field used: |
|
|
Replaced with the path value for the document. Index field used: |
|
|
Replaced with the file name for the document (including the extension). Index field used: |
|
|
Replaced with the document’s creation time. Index field used: |
|
|
Replaced with the document’s last modified time. Index field used: |
|
|
Replaced with the system prompt. |
Document text limit: how many characters of each document's text are sent. 0 sends all of it. Lower it if long documents are slow or fail: a model reads only as much as its context window holds.
A prompt can't be saved until it uses at least one document placeholder: {{text}}, {{name}}, {{path}}, {{created}} or {{modified}}.
Example
Document to check:
{{text}}
You can also add follow-up instructions after the injected text if needed, such as "Return results in JSON format" or "Respond with field values only." which can help with older or smaller parameter models.
To get started, we recommend the following configurations based on your use case. These are starting points, prompts and model choice may need to be refined given your data.
Try to use the Source selection & Query conditions in the prompt card to limit the content the model is analyzing to save processing time on irrelevant content.
Step 5 - Set Query Conditions
Query conditions let you control when an enrichment should run. Only files that meet all conditions will be sent to the model.
Each condition checks metadata about the file. Some examples:
|
Field |
Operator |
Example Value |
|---|---|---|
|
|
|
Ensures the file has extracted text |
|
|
|
|
|
|
|
|
|
|
|
(Avoid re-processing already enriched files where the field |
You can add multiple conditions to narrow down processing scope.
We recommend these conditions at minimum. New prompts start with fullText exists and path-valid is not false.
|
Field |
Operator |
Value |
|---|---|---|
|
|
|
Ensures the file has extracted text |
|
|
|
Skips documents the prompt has already answered. Use one of the prompt's own result fields, such as |
|
|
|
During Shinydocs Pro’s delta analysis, it checks if a file still exists or not. Adding this condition prevents the tool from running on data that doesn’t exist anymore. |
Step 6 - Ignored Responses
Define any values that should be treated as a non-result and skipped from enrichment output. For example:
-
N/A -
[N/A] -
NA
Each field is checked on its own. If the model's answer for a field is exactly one of these values (matching is case-sensitive), that field is left empty; the other fields are still saved.
Enter them in Answers to ignore, separated by commas. New prompts start with N/A, [N/A], N\A, [N\A]. Adjust them to match how your model responds.
Step 7 - Define Result Fields
This section is where you map out what you want the AI to extract from the document and where that extracted information will be stored.
When the model processes a document, it doesn't just give you raw text back. Instead, it responds with a structured result, a set of named fields, like client, matter_number, or custom_description. Shinydocs Pro prefixes these fields with ai-text-analysis-, that way you know this field’s data came from AI enrichment. The values the model returns for those fields get saved as metadata alongside the document in the Shinydocs index. That means they can be searched, filtered, visualized, or exported just like any other metadata.
You’re telling the system: “Here’s what I expect back from the AI, and this is what type of data it should be.”
How it works
You're setting up the schema for what the AI should return - field names, their data types, and whether they're required. This tells the system how to handle the response, and it tells the model what kind of format you're expecting.
The results of AI Enrichment are dependent on the chosen model. Different models will respond in different ways, which is why choosing the right model for the task at hand is so important. Most models will respect the instructions you provide it, but will vary model-by-model. Experimentation is key!
Each field definition includes:
-
Field name: This is the name that will be stored in the index. Shinydocs will automatically prefix it with
ai-text-analysis-.-
For example,
clientbecomesai-text-analysis-client.
-
-
Field type: The expected data format of the returned value. Options include:
-
Text: A single piece of text (most common).
-
Number: A numeric value (integer or decimal).
-
Yes or no:
trueorfalse. -
List of text: A list of values (e.g. a list of names, IDs, keywords).
-
When to use
array:The
arraytype is used when you expect the model to return multiple items for the same field, for example:-
A list of people mentioned in the document
-
Multiple project codes or legal clauses
-
A list of risks or key terms
-
-
-
-
Required: required fields are always answered. The model can leave the other fields empty.
Example field setup
|
Field Name |
Type |
Required? |
|---|---|---|
|
|
Text |
✅ Yes |
|
|
List of text |
❌ No |
In this case:
-
client_nameis required, so the model always answers it. Ask it in the system prompt to answer N/A when it can't find a client, and keep N/A in Answers to ignore, so the field is left empty instead of guessed. -
related_tagsis optional because it's supplemental. The model might extract useful keywords, topics, or flags if they exist, but you're not relying on them to validate the result. If they're missing or the document doesn't contain any, that’s fine, you still want to keep the enrichment.
Step 8 - Save
Select Save changes, or Discard changes to undo edits you haven't saved. The prompt runs the next time each of its sources runs its analysis (for example, with Run now on the source page), on the documents that match its conditions.